

In recent years, GTC headlines have focused on faster GPUs, increased FLOPS, steeper scaling, and rising capital expenditure thresholds.
This year marks a notable shift.
According to NVIDIA, GTC 2026 centers on AI factories, agentic AI, and inference. The focus is moving from building stronger GPUs to delivering systems that run inference at scale, reliably, and at lower cost.
GTC 2026 will take place March 16–19 in San Jose. The official agenda highlights AI factory architecture and inference efficiency as primary topics.
The most significant developments are unlikely to be new chip announcements. Instead, attention should focus on several structural themes: Vera-Rubin for agentic AI, Rubin CPX for high throughput inference, Groq LPU for low latency inference, Feynman, CPO/photonics, and an AI-native storage hierarchy.
The central theme this year is likely the systemization of inference.
Training remains important, but capital markets are increasingly focused on inference. Training enables model creation, while inference drives business value. Training represents an episodic capital expenditure; the inference is ongoing operating expense.
As agentic workflows, long-context coding, enterprise retrieval, and multimodal video workloads expand, system KPIs are evolving. Peak FLOPS are becoming less relevant, while metrics such as TTFT, tail latency, tokens per second, tokens per watt, and cost per token are gaining importance. NVIDIA’s messaging for Rubin, Dynamo, BlueField-4, and optics increasingly emphasizes these operational metrics.
For this reason, GTC 2026 should be evaluated from a systems perspective rather than focusing solely on chips. The primary question is whether NVIDIA will formalize inference as a decomposed, scheduled, factory-managed pipeline.
Two weeks ahead of GTC, Nvidia announced that it will invest approximately $2 billion each in Lumentum and Coherent (about $4 billion in total) as strategic investments, alongside multi-year, multi-billion-dollar purchase commitments. The move is intended to accelerate the development and supply of photonics/optical interconnect and laser component technologies within its AI data center infrastructure — representing a core commitment to the massive interconnect demands of future AI factories.
Vera Rubin: From “GPU” to “AI Factory Unit”
Rubin’s significance lies not in outperforming Blackwell but in NVIDIA’s redefinition of the product boundary.
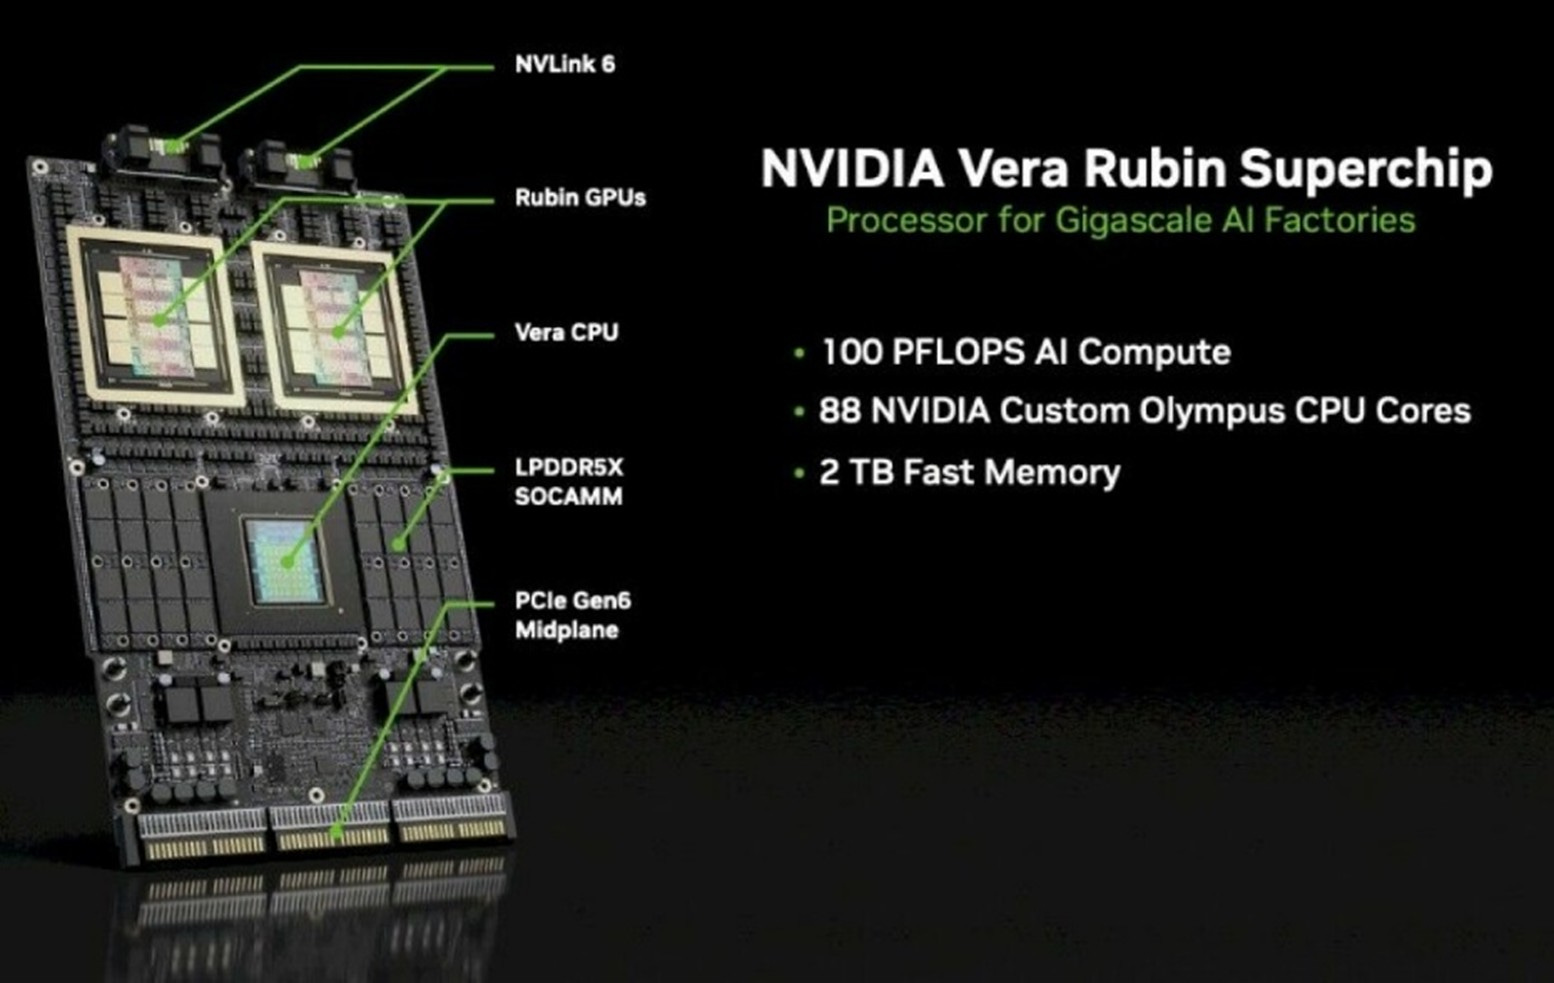
In January, NVIDIA introduced the Rubin platform as an integrated AI supercomputing stack composed of Vera CPU, Rubin GPU, NVLink 6 switch, ConnectX-9 SuperNIC, BlueField-4 DPU, and Spectrum-6 Ethernet. The stated goal is clear: reduce token cost and compress the GPU footprint required for large MoE training and inference.
NVIDIA is shifting from selling standalone GPUs to offering a vertically integrated AI factory platform, with compute, networking, security, and memory control tightly integrated.
The market’s focus is shifting from card counts to rack-scale configurations such as NVL72, NVL144, and NVL576. The significance of NVL576 is not its size, but its indication of architectural evolution from cable-heavy aggregation to orthogonal backplane, system-optimized, and serviceable rack designs. We expect orthogonal backplane concepts — widely discussed across the ecosystem — to become more visible at GTC 2026, reinforcing this transition toward signal-integrity-driven, rack-native architectures.
At this year’s GTC, we expect four primary Vera Rubin rack configurations to emerge:
Vera Rubin NVL72 – Architecturally similar to GB200/GB300 NVL72, using copper interconnects within the rack and a single layer of NVSwitch for internal switching.
Vera Rubin NVL144 – Likely to adopt an orthogonal backplane design, effectively forming a much larger, more integrated rack-scale system.
Vera Rubin NVL576 – Composed of eight Vera Rubin NVL72 units. The first layer would be interconnected via copper, while the second layer would leverage CPO-based NVSwitch interconnect. This would be a symbolic milestone, marking CPO’s formal entry into scale-up architectures. We will discuss this in more detail later.
Vera CPU Rack – There have been prior reports that Meta plans to procure NVIDIA’s Vera CPU rack product. We expect NVIDIA to formally launch this configuration at GTC. As discussed previously, CPUs increasingly serve as a bottleneck for agentic AI workloads, and the Vera CPU Rack is designed to address that constraint.
Once procurement moves from board-level to rack-level, value naturally diffuses. It extends beyond GPUs into backplanes, switching boards, power delivery, thermal design, materials, and internal interconnect. This is the structural backdrop for why CPO and AI storage architecture are becoming increasingly relevant.
Rubin CPX with HBM: Formalizing Prefill as a Product Category for High Throughput Inference
While Rubin serves as the AI factory base layer, Rubin CPX introduces a structural shift within the inference pipeline.
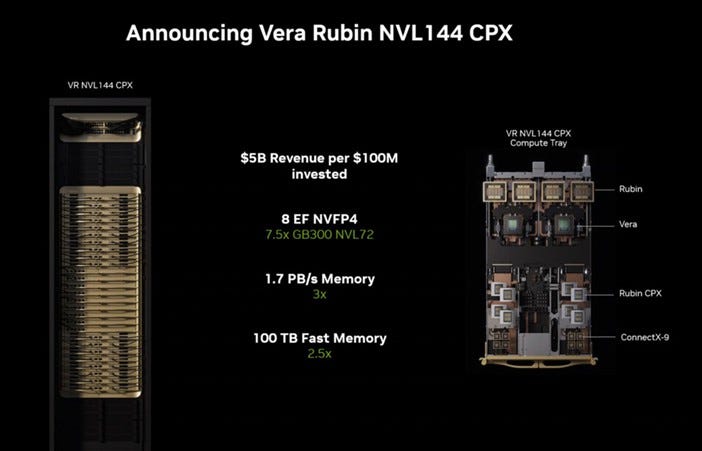
In September 2025, NVIDIA introduced Rubin CPX as a GPU class optimized for massive-context inference. The positioning was explicit: million-token coding workloads and generative video. The Vera Rubin NVL144 CPX configuration reportedly delivers 8 exaflops of AI performance per rack, 100TB of fast memory, and 1.7 PB/s of bandwidth.
This development goes beyond a simple SKU expansion. It acknowledges, architecturally, that long-context prefill is distinct enough to warrant specialization.
Historically, the market assumed inference could be addressed with larger GPUs and additional HBM. Rubin CPX challenges this view. Prefill and decode require different memory-access patterns, bandwidth, and latency considerations. Long-document ingestion, video understanding, and million-token contexts now justify specialized compute pathways.
Channel checks indicate that Rubin CPX, initially positioned without HBM, is now incorporating HBM to meet high-bandwidth requirements.
Rubin CPX is expected to handle the prefill stage, while the standard Rubin GPU focuses on decode, targeting high-throughput inference workloads.
In other words, CPX is optimized for long-context ingestion and memory-intensive prefill operations, whereas the core Rubin GPU is tuned for scalable, throughput-driven token generation across large concurrent workloads.
Groq LPU: not a replacement for GPU+HBM, but a low-latency inference extension that expands NVIDIA’s TAM
Groq is expected to be a prominent topic at GTC 2026, but it is also susceptible to misinterpretation.
